Allowed Model Pools: How Enterprises Control Which Models Process Their Data
September 16, 2026
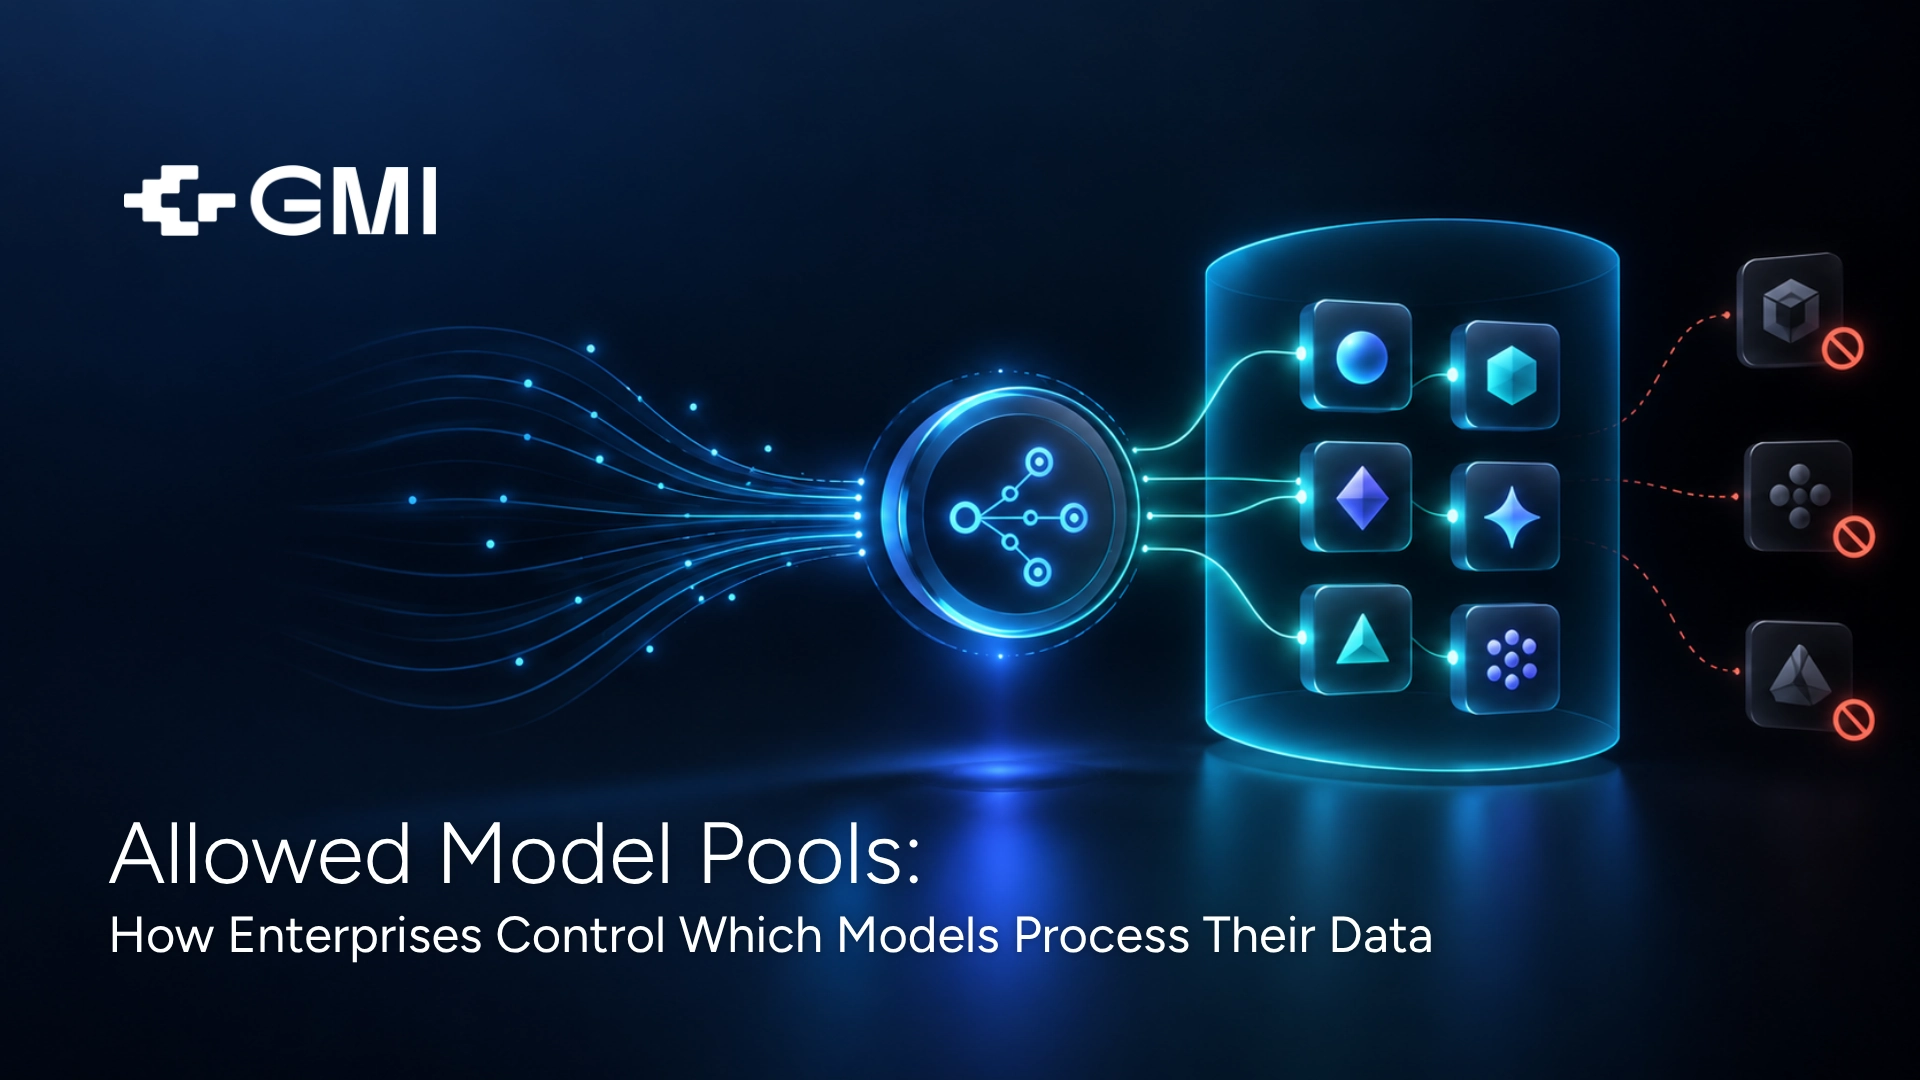
Most enterprise AI governance programs have a model approval process and no mechanism to enforce its output. Security review evaluates a model, legal reviews the data processing terms, the governance committee approves it, and the result is a list in a policy document. Nothing in the runtime stack reads that document. A developer who calls an unapproved model does not encounter an error; they encounter a working API. The gap between the approved list and what actually runs is where most enterprise AI compliance failures originate, and it widens as model routing makes model selection automatic rather than explicit. An allowed model pool closes that gap by converting the approved list from a policy artifact into a technical constraint enforced at request time.
- Policies without technical gates are not controls. Enterprise AI governance guidance in 2026 is consistent on this point: data loss prevention rules, endpoint allowlisting for approved AI tools, and runtime controls for model outputs constitute the minimum technical layer. A model approval list that exists only in documentation is documentation, not enforcement.
- GMI Router implements the allowed model pool as a runtime constraint. Model selection draws only from the configured pool, and critically, fallback candidates are selected from the same pool during the recommendation phase rather than at failure time.
- The failure-time edge case is where most allowlist implementations break. A routing system that selects the most available model during an incident, rather than the most compliant one, produces a governance violation at exactly the moment the system is already degraded. Pre-selecting fallbacks from the approved pool is what prevents this.
- Shadow AI has a model-level form that inventory tools miss. Discovery tools find unapproved AI applications and unsanctioned MCP connections. They do not find an approved application calling an unapproved model through an approved gateway, because the traffic looks legitimate at every layer except the model identifier.
- Pool structure should mirror data classification, not organizational convenience. A single global allowlist forces the most restrictive requirement onto every workload. Tiered pools by data sensitivity allow low-sensitivity workloads access to the full model catalog while restricting regulated data to the subset that has cleared the applicable review.
- The pool is audit evidence. Auditors want a complete inventory of AI in use and evidence that each system passed risk assessment before going live. The pool configuration plus the routing metadata log together demonstrate which models were approved and which actually processed data.
The Gap Between Approval and Enforcement
Enterprise AI governance maturity is commonly described in four stages. Stage 1 is discovery: building the inventory and finding the shadow AI that leadership did not know existed. Stage 2 is operational governance: policies written, ownership assigned, risk assessments run before deployment, with controls that are largely manual. Stage 3 is lifecycle governance with automated monitoring and continuous runtime enforcement, which is where most large enterprises should be targeting by end of 2026. Stage 4 embeds governance into engineering workflows, procurement, and vendor contracts.
The transition from Stage 2 to Stage 3 is where allowed model pools matter, because it is the transition from manual to enforced.
What Stage 2 looks like in practice.
The governance committee approves a model. The approval is recorded in the AI registry. A policy document states which models are approved for which data classifications. Engineering teams are informed.
Enforcement depends on engineers reading the policy, remembering which models are approved, and configuring their applications accordingly. When a new model is released and a developer wants to try it, nothing prevents the attempt. When a model is removed from the approved list after a vendor terms change, nothing removes it from running applications.
The risk at this stage is inconsistent enforcement across business units, which is the standard characterization of Stage 2 maturity. One team follows the policy precisely; another has a service calling a model that was approved two years ago and has since been deprecated from the list.
What runtime enforcement changes.
An allowed model pool configured at the platform level means the approved list is the runtime configuration. A request specifying an unapproved model fails. A routing decision cannot select an unapproved model. A fallback cannot escape to an unapproved model during an incident.
The policy document and the runtime behavior are the same artifact rather than two artifacts that drift apart.
Model-Level Shadow AI
Shadow AI is usually defined as any AI tool, agent, or connection an employee runs without IT approval or security review. Discovery tools search for unsanctioned SaaS AI applications, personal API keys on endpoints, and rogue MCP server connections.
There is a form of shadow AI at the model level that this discovery misses entirely.
The pattern. An application that is fully approved (in the inventory, risk-assessed, owned by a named system owner) calls a model that is not on the approved list. The application is legitimate. The gateway is legitimate. The API key is corporate. The traffic passes every network and endpoint control. The only thing wrong is the model identifier in the request body.
Why it happens without malice. A new model releases with better benchmarks. A developer updates the model string in a configuration file to test it, measures an improvement, and leaves it. The change passes code review because reviewers focus on logic rather than model identifiers. Six months later, an audit asks which models process customer data, and the answer includes a model nobody reviewed.
Why discovery tools miss it. Endpoint allowlisting controls which AI services can be reached. It does not inspect which model is requested within an allowed service. A model gateway that permits any model in the provider's catalog permits the unapproved ones alongside the approved ones.
What catches it. Two mechanisms. An allowed model pool enforced at the gateway or routing layer rejects the request. Routing metadata logging records the model that actually ran, which makes the discrepancy visible in audit even if enforcement is not in place.
Pool Structure: Tiering by Data Classification
The instinct is to configure one organizational allowlist. This forces the most restrictive requirement onto every workload, which produces a predictable outcome: teams working with non-sensitive data find the allowlist too restrictive for their needs and route around it.
The tiered approach.
Structure pools to match data classification tiers, with each tier's pool containing the models that have cleared the review appropriate to that classification.
Tier 1, public and non-sensitive data. Marketing copy generation, public documentation summarization, internal tooling that processes no customer or employee data. Pool: the full model catalog, or the subset excluding models with unacceptable terms of service. Review requirement: minimal.
Tier 2, internal confidential data. Internal documentation, non-regulated business data, proprietary technical content. Pool: models with acceptable data processing agreements and no training-on-customer-data provisions. Review requirement: contract review of the data processing terms.
Tier 3, regulated personal data. Customer PII, employee data, data subject to GDPR or sector-specific frameworks. Pool: models with signed DPAs, documented data residency, and zero-retention or contractually limited retention. Review requirement: full vendor risk assessment plus legal review.
Tier 4, highly regulated data. Protected health information, financial records subject to SOX, government or defense data. Pool: models with BAAs where applicable, single-tenant deployment options, and jurisdictional compliance verified. Review requirement: full assessment plus, in many cases, dedicated infrastructure rather than shared inference.
Why this structure works better than a single pool.
It matches enforcement strictness to actual risk. A team building an internal documentation search tool is not constrained by the requirements that apply to the team processing patient records. The permissive tier reduces the incentive to circumvent the control, which is the primary failure mode of over-restrictive governance.
It also makes the approval process tractable. A model needs review only against the tier where a team wants to use it, rather than against the strictest requirement in the organization.
Implementation. In GMI Router, this maps to configuring different allowed model pools per workspace, with workspaces aligned to data classification rather than to teams. A team working across multiple data classifications uses multiple workspaces with different pools.
The Failure-Time Governance Gap
This is the specific edge case where allowlist implementations most commonly break, and it is worth understanding in detail because the failure is silent.
The scenario. A routing system has an allowed model pool. The primary model for a request is selected from the pool correctly. During generation, the primary model returns a rate limit error. The routing system needs a fallback.
The naive implementation. At failure time, the routing system queries available models, finds one with capacity, and retries. The model it finds may or may not be in the allowed pool, because the query was for availability rather than for compliance.
The request succeeds. The application receives a valid response. The failure was handled gracefully. An unapproved model processed the organization's data, and unless routing metadata records it, nobody knows.
Why this is worse than an ordinary policy violation. It occurs precisely during degraded conditions, which correlate with high load, which correlate with high traffic volume. The violation is not one request; it is potentially a large fraction of traffic during the incident window.
The correct implementation. Fallback candidates are selected during the recommendation phase, from the same allowed pool, before any failure occurs. When a failure triggers fallback, the pre-selected candidate applies. There is no availability query at failure time that could escape the pool.
GMI Router implements this: the recommendation phase selects one primary model and two fallback candidates simultaneously, all constrained by the same Model Scope, Price Tier, and Allowed Models settings. As covered in GMI Cloud's article on primary and fallback models, pre-selecting fallbacks from the approved pool is what keeps governance intact under failure conditions.
The pool-exhaustion case. If the allowed pool does not contain enough eligible models to support a primary plus fallbacks, the correct behavior is an explicit error asking the administrator to expand the pool, not a silent expansion beyond the pool. A system that quietly relaxes the constraint when it cannot satisfy it provides no governance guarantee at all.
The Three Pool Controls and What Each Governs
GMI Router exposes three distinct constraints that compose. Understanding what each governs prevents configuring the wrong one for a given requirement.
Model Scope: All, Open Source Only, or Closed Source Only.
This governs the license and weight availability dimension. Open Source Only is the setting for organizations whose governance requires that model behavior be reproducible and auditable from published weights, or that retain the option to self-host the same model if vendor terms change.
Closed Source Only is less common but appears in organizations where specific closed models have cleared security review and open-weight models have not been assessed. It is also the configuration for teams that require vendor-backed SLAs and support that open-weight self-service deployment does not provide.
Price Tier: Low, Medium, High, or All.
This governs the cost dimension, calculated from blended price across the catalog: Low is the bottom third by price, Medium the middle third, High the top third.
Price Tier is a cost control rather than a compliance control, but it interacts with governance in one useful way: restricting an internal tooling workspace to the Low tier prevents an experiment from consuming the budget allocated to customer-facing production workloads.
Allowed Models: an explicit whitelist.
This is the compliance control. A checkbox list of specific models that this workspace may use. Selection and fallback both draw only from this list.
The three constraints compose: a workspace configured with Open Source Only, Medium Price Tier, and a specific Allowed Models list can select only models that satisfy all three. The Allowed Models list is the most specific and typically the operative constraint for regulated workloads.
Default behavior when unconfigured. When Allowed Models is not configured, the system uses a default pool. For a governance program, this default is the setting that matters most to review, because an unconfigured workspace is running on whatever the default permits. Explicit configuration for every workspace that processes non-public data should be a governance requirement rather than an option.
Operating the Pool: Review Cadence and Change Management
An allowed model pool is a living configuration, and the operational questions are when to add, when to remove, and who decides.
Adding a model.
The trigger is usually a team request: a new model released, benchmarks look strong, a team wants to evaluate it. The process should distinguish evaluation from production use.
Evaluation on non-sensitive data can proceed in a Tier 1 workspace with a permissive pool, which allows teams to test new models without a full review. Promotion to a restricted tier requires the review appropriate to that tier.
This two-stage structure prevents the review process from becoming a bottleneck that teams route around, while keeping regulated data behind the full assessment.
Removing a model.
Three triggers: the vendor changes terms in a way that fails the review that originally approved it, the model is deprecated by the provider, or operational data shows the model performing poorly on the workloads that route to it.
Removal has a practical complication under routing: a model removed from the pool stops receiving traffic immediately, which redistributes that traffic to the remaining models. This can shift cost and quality in ways that are worth monitoring after the change. The routing distribution before and after a pool change is the metric to watch.
Review cadence.
Quarterly review of each pool against the current model catalog is a reasonable default. The review covers: models in the pool that have been deprecated or whose terms changed, models in the catalog that teams have requested and that have cleared review, and the routing distribution to identify models in the pool that receive no traffic and could be removed to simplify the configuration.
Organizations tracking 150 to 500 or more models in production need this cadence to be automated rather than manual, with the review surfacing exceptions rather than requiring full re-examination.
Ownership.
A common RACI structure for model approval: the AI Governance Council is accountable, a Model Risk Owner is responsible, Legal and Compliance and the Data Steward are consulted, and the Product or Business Owner is informed. The pool configuration should be changeable only by the responsible role, with changes logged.
The Pool as Audit Evidence
Auditors want to see three things: a complete inventory of AI systems in use, evidence that each went through risk assessment and approval before going live, and evidence of ongoing monitoring.
The allowed model pool contributes to the first two directly and enables the third.
Inventory. The pool configuration is a list of models approved for a given data classification, with the approval decision traceable to the review that produced it. Combined across workspaces, the pools constitute the model-layer inventory.
Approval evidence. The pool membership is the enforcement artifact that corresponds to the approval decision. An auditor asking "how do you ensure only approved models process customer data" has a technical answer rather than a policy answer.
Ongoing monitoring. The routing metadata log records the model that actually processed each request. Joining this to the pool configuration demonstrates that runtime behavior matched the approved configuration over the audit period. A discrepancy between the two is itself the finding.
The accountability point that governance guidance emphasizes. Vendor documentation is useful for due diligence and for the BAA, but it replaces none of your own risk assessment, monitoring, or human oversight obligations. Under GDPR, HIPAA, and most sector regulations, the deploying organization remains the accountable party regardless of who built the model. The allowed model pool is part of how the deploying organization demonstrates that accountability was exercised.
Pool Configuration for Agentic Systems
Agentic systems introduce a specific complication: an agent makes many model calls across its execution, and different steps may benefit from different models.
The straightforward case. A single agent role using one model for all steps. The pool constraint applies identically to every call, and configuration is the same as for a conversational application.
The step-level routing case. An agent that uses a smaller model for classification and routing steps and a larger model for reasoning and synthesis steps. The pool must contain both, and the governance question is whether both have cleared review for the data classification the agent handles.
A common configuration error: approving the large model for regulated data because it is the one that produces the user-visible output, while the smaller classification model also processes the same data and was approved only for a lower tier. Every model in the agent's execution path processes the data, regardless of whether its output reaches the user.
Multi-agent systems. Each agent role may have its own model requirements. The pool applies per workspace, which means either all agents in a pipeline share the same pool, or the pipeline spans workspaces with different pools and the orchestration layer must handle that.
The simpler configuration for governance purposes: one workspace per data classification, with all agents processing that classification operating within the same pool. On GMI Agentbox, Model Scope and Allowed Models settings restrict which models the deployed agents can access, which applies the same constraint across the agent's full execution path.
Two Layers of AI Governance and Where Pools Fit
Enterprise AI governance is usefully split into two layers that answer different audit questions.
Layer 1: model and policy governance. Proves a model is documented, assessed, and approved. Includes the AI registry, bias and risk assessment, and regulatory framework mapping. Answers: is this model approved for this use?
Layer 2: agent governance. Proves an agent acted within its scoped rights in approved environments. Includes agent identity, application-aware permissions, an MCP gateway, and shadow AI discovery. Answers: did this agent do only what it was permitted to do?
Allowed model pools sit at the boundary. The pool membership is a Layer 1 artifact: it encodes the approval decisions. The runtime enforcement is a Layer 2 mechanism: it constrains what the system can actually do at execution time.
This positioning is why the pool is more valuable than a policy document listing the same models. The document is Layer 1 only. The enforced pool is Layer 1 evidence with Layer 2 enforcement, which is the combination that satisfies both the "is it approved" and "did it act within scope" audit questions.
The Implementation Sequence
For organizations moving from a policy-based approved list to an enforced pool, four steps.
Step 1: Map data classifications to pool tiers. Identify how many distinct data classifications the organization's AI workloads handle. Most organizations need three or four tiers. Fewer forces over-restriction; more becomes unmanageable.
Step 2: Assign models to tiers based on completed reviews. For each model currently in use or approved, determine the highest data classification tier its review supports. Models without a completed review for a given tier do not enter that tier's pool, even if they are widely used.
This step frequently reveals that models in production use have not been reviewed for the data classification they are processing, which is the finding that motivates the exercise.
Step 3: Configure workspaces by classification and apply pools. Align workspaces to data classifications rather than to teams. Configure the Allowed Models list for each workspace to the corresponding tier's pool. Verify that Model Scope and Price Tier settings do not inadvertently exclude approved models.
Step 4: Verify enforcement, including at failure time. Test that a request specifying a model outside the pool is rejected. Test that routing does not select outside the pool. Test the fallback path specifically: force a primary model failure and verify the fallback that applies is within the pool.
The fourth step is the one most commonly skipped and the one that verifies the property that matters most, because failure-time behavior is where allowlist implementations break.
For teams planning the broader move to routing, GMI Cloud's model routing guide covers how the pool constraint interacts with the cost, quality, and reliability dimensions of the routing decision.
Conclusion
The distance between an approved model list and what actually processes an organization's data is the distance between policy and enforcement. Governance guidance in 2026 is consistent that policies without technical gates are insufficient, and that runtime controls are the minimum technical layer. An allowed model pool is that gate for the model selection decision.
Three implementation properties determine whether the pool provides a real guarantee. It must be enforced at the routing or gateway layer rather than depending on developer configuration. It must apply to fallback selection as strictly as to primary selection, with fallback candidates pre-selected from the pool rather than found at failure time. And when the pool cannot satisfy a request, it must fail explicitly rather than silently expanding beyond the approved set.
Structured by data classification rather than as a single organizational allowlist, the pool matches enforcement strictness to actual risk, which reduces the incentive to route around the control. Combined with routing metadata logging, the pool configuration becomes audit evidence: the list of what was approved, and the record of what actually ran.
FAQs
Why is a documented approved model list insufficient for enterprise AI governance? Because nothing in the runtime stack reads the document. A developer who calls an unapproved model encounters a working API rather than an error, and the change passes code review because reviewers focus on logic rather than model identifiers. Enterprise AI governance guidance in 2026 characterizes this as the Stage 2 maturity risk: policies written and ownership assigned, but controls that are largely manual, producing inconsistent enforcement across business units. Runtime enforcement through an allowed model pool makes the policy document and the runtime behavior the same artifact rather than two artifacts that drift apart.
What is model-level shadow AI and why do discovery tools miss it? Model-level shadow AI is an approved application calling an unapproved model through an approved gateway. The application is in the inventory, the API key is corporate, and the traffic passes every network and endpoint control. The only non-compliant element is the model identifier in the request body. Discovery tools search for unsanctioned AI applications, personal API keys, and rogue MCP connections, but endpoint allowlisting controls which AI services can be reached rather than which model is requested within an allowed service. Two mechanisms catch it: an allowed model pool that rejects the request at the routing layer, and routing metadata logging that records the model that actually ran.
How should allowed model pools be structured for an organization with multiple data classifications? Tier the pools by data classification rather than configuring one organizational allowlist. A single global pool forces the most restrictive requirement onto every workload, which causes teams working with non-sensitive data to route around the control. A typical four-tier structure: public and non-sensitive data with a permissive pool, internal confidential data requiring acceptable data processing terms, regulated personal data requiring signed DPAs and documented residency, and highly regulated data requiring BAAs and often dedicated single-tenant infrastructure. This matches enforcement strictness to actual risk and makes the approval process tractable, because a model needs review only against the tier where a team wants to use it.
What is the failure-time governance gap in model allowlisting? It is the edge case where a routing system with an allowed pool selects a fallback model at failure time by querying for availability rather than compliance. The primary model fails, the system finds an available alternative, the request succeeds, and an unapproved model processed the organization's data with no visible error. This is worse than an ordinary policy violation because it occurs during degraded conditions that correlate with high traffic volume, so the violation may affect a large fraction of requests during the incident window. The correct implementation pre-selects fallback candidates during the recommendation phase from the same allowed pool, so no availability query at failure time can escape the constraint.
How does an allowed model pool function as audit evidence? Auditors want a complete inventory of AI in use, evidence that each system passed risk assessment before going live, and evidence of ongoing monitoring. The pool configuration contributes to the first two directly: it is a list of models approved for a given data classification, traceable to the review that produced each approval, and it is the technical enforcement artifact corresponding to that approval decision. For ongoing monitoring, joining the routing metadata log (which records the model that actually processed each request) to the pool configuration demonstrates that runtime behavior matched the approved configuration over the audit period. Any discrepancy between the two is itself the audit finding.
Build AI Without Limits
GMI Cloud helps you architect, deploy, optimize, and scale your AI strategies
FAQ
Because nothing in the runtime stack reads the document. A developer who calls an unapproved model encounters a working API rather than an error, and the change passes code review because reviewers focus on logic rather than model identifiers. Enterprise AI governance guidance in 2026 characterizes this as the Stage 2 maturity risk: policies written and ownership assigned, but controls that are largely manual, producing inconsistent enforcement across business units. Runtime enforcement through an allowed model pool makes the policy document and the runtime behavior the same artifact rather than two artifacts that drift apart.