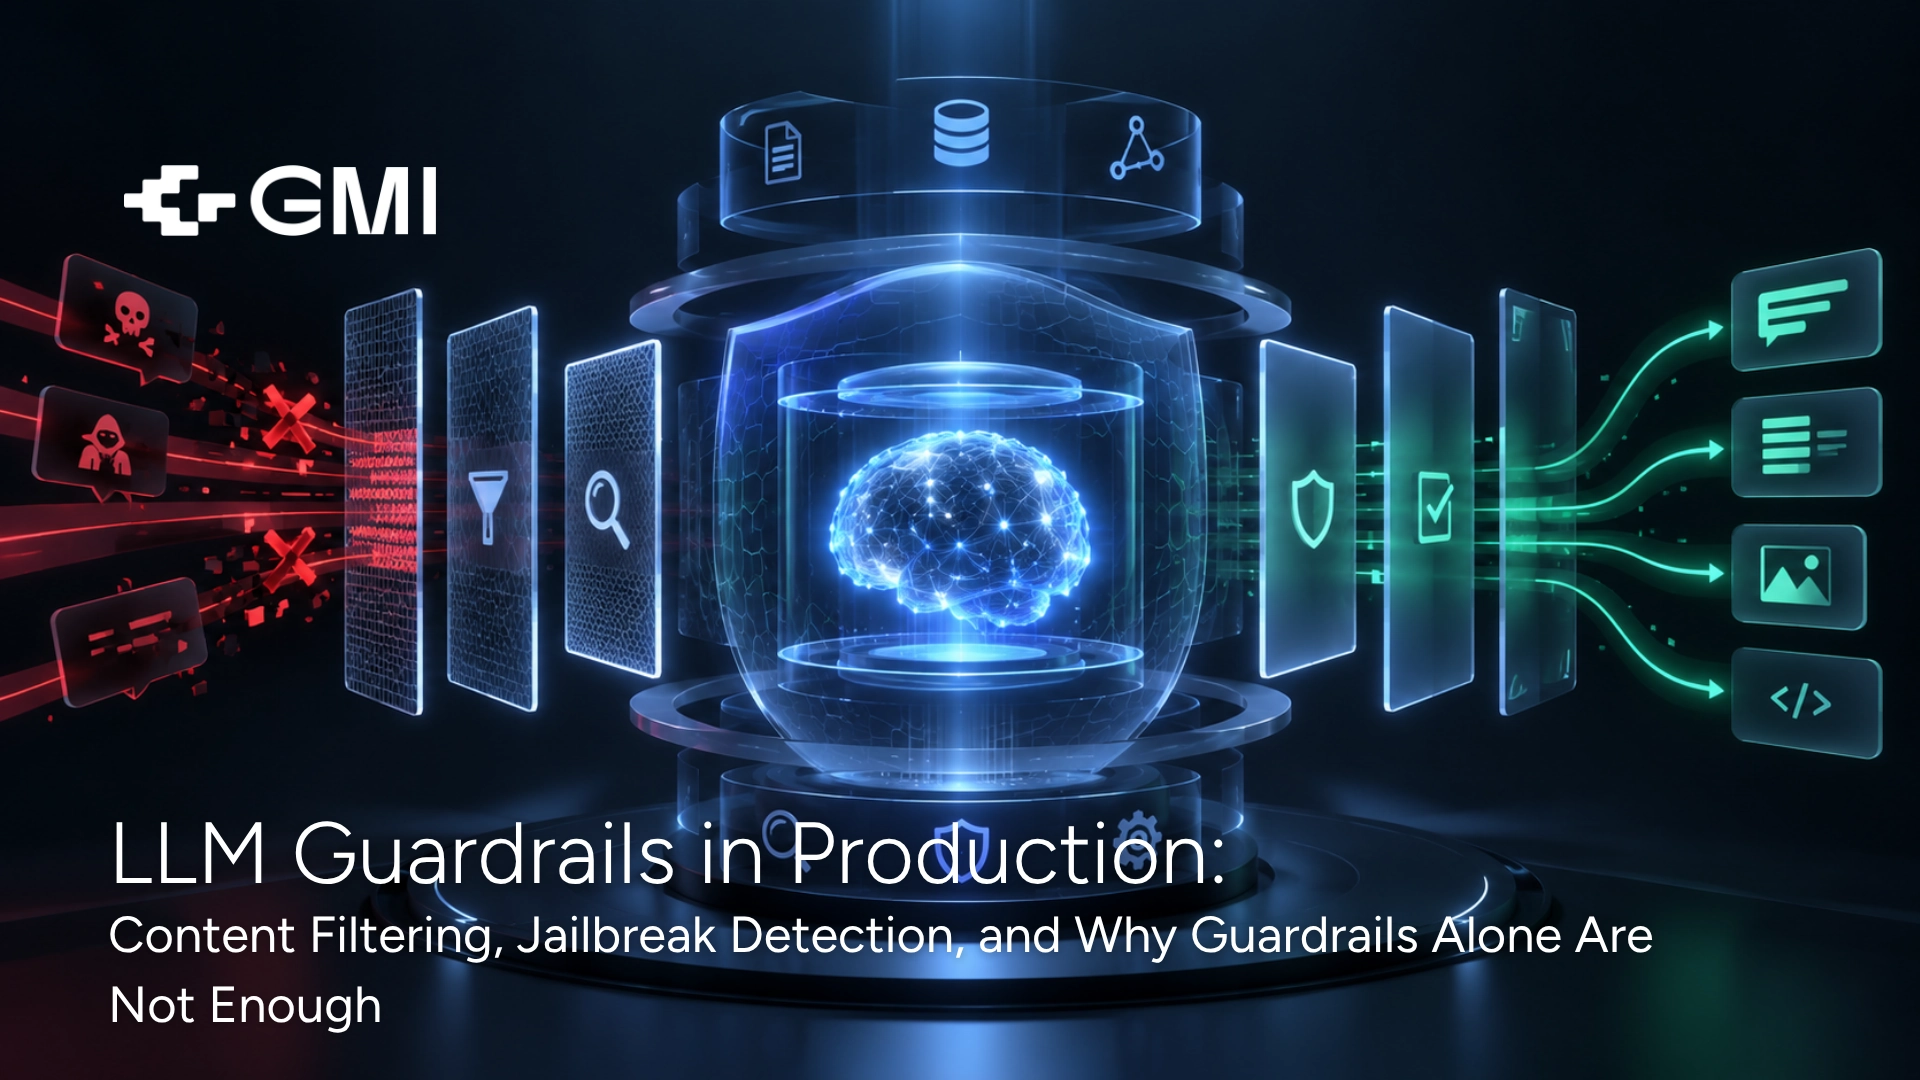
LLM Guardrails in Production: Content Filtering, Jailbreak Detection, and Why Guardrails Alone Are Not Enough
September 16, 2026
Guardrails are the standard answer to LLM safety in production: put a classifier in front of the model to catch malicious prompts, put another behind it to catch harmful outputs, and the application is protected. The demo is convincing, the attack-block numbers look strong, and the deployment ships. The problems appear afterward, in two directions at once. Academic research published across 2025 and 2026 demonstrated evasion success rates approaching 100 percent against six prominent guardrail systems, including Microsoft's Azure Prompt Shield and Meta's Prompt Guard, using character injection and adversarial machine learning techniques. In the other direction, a classifier tuned aggressively enough to catch those attacks starts refusing legitimate requests, and a safety layer that blocks one in three real users is an outage with extra steps.
- Guardrails reduce the frequency of successful attacks. They do not eliminate the attack surface. OWASP's own guidance treats guardrails as one layer in a defense-in-depth design, not as the control that makes an LLM application safe.
- The production stack is multiple specialized classifiers, not one general-purpose moderator. A typical 2026 configuration runs a fast first-pass gate (Llama Prompt Guard 2 at 86M parameters, 20 to 50ms on H100) ahead of a detailed hazard classifier (Llama Guard 3 8B), orchestrated by a policy layer such as NeMo Guardrails. Total overhead is approximately 90 milliseconds.
- GMI Prime Inference provides the dedicated capacity guardrail classifiers require. Guardrail models sit on the critical path of every request, which means their latency variance is the application's latency variance. Cold starts on a guardrail classifier are as damaging as cold starts on the primary model.
- Adversarial robustness is the metric that separates real options from demos. Llama Guard 4 achieves F1 of 0.961 on clean data and 0.796 under adversarial inputs, at approximately 459ms p95 latency on typical GPU hardware. That gap is why production deployments pair it with a faster specialized classifier rather than relying on it alone.
- Input-only classifiers do not catch indirect injection. When adversarial content arrives through a RAG document, a fetched web page, or a tool result, an input classifier inspecting the user message sees nothing wrong. Retrieval rails and output sanitization are required for that attack class.
- The false positive rate determines whether the guardrail ships. Llama Guard 3 exists in large part because general-purpose models used as moderators refuse too many legitimate requests. It posts roughly one third the false positive rate of GPT-4 as a moderator on Meta's benchmark.
What Guardrails Actually Are
A guardrail is a programmatic control wrapped around a model that validates input before the model sees it, filters or rewrites output before the user sees it, and gates what actions the model can trigger. In production this decomposes into distinct rail types with different placements and different failure modes.
Input rails. Run before the prompt reaches the model. Catch direct prompt injection attempts, jailbreak patterns, off-topic requests, and PII in user input that should be masked before processing. These are the rails most teams implement first because the placement is obvious.
Retrieval rails. Run after retrieval and before the prompt is assembled, filtering what context chunks from a RAG pipeline can be injected into the prompt. These catch the attack class that input rails miss entirely: adversarial instructions planted in a document that the retrieval layer surfaces.
Dialog rails. Govern conversation flow across turns: which topics the model may discuss, when it must escalate to a human, what multi-turn patterns are prohibited. NeMo Guardrails implements these through its Colang DSL, defining rails as conversation patterns rather than individual checks.
Output rails. Run after generation and before the response reaches the user. Catch harmful content the model produced, PII that leaked from training data or context, and system prompt disclosure.
Tool call rails. For agentic systems, pre-execution rails validate the function name and parameters before the call executes, and post-execution rails inspect tool results before they are re-injected into context. This is the rail type that matters most for agents and the one most commonly missing.
Execution rails. Sandbox constraints on code execution, network egress restrictions, and resource limits. These are infrastructure controls rather than classifier-based rails, and they are the layer that holds when the classifier-based rails are bypassed.
The Tool Landscape and What Each Solves
The naming in this space causes confusion, because tools with similar names solve different problems and are frequently deployed together rather than as alternatives.
| Tool | What it is | Typical latency | Best for |
|---|---|---|---|
| LLM Guard | Local scanner, no LLM call required | Under 10ms per check | Fast first-layer scanning at high throughput |
| Llama Prompt Guard 2 | 86M parameter injection classifier | 20 to 50ms on H100 FP8 | Fast first-pass injection gate |
| Llama Guard 3 / 4 | 8B open-weight safety classifier | Llama Guard 4: ~459ms p95 | Detailed hazard classification with category codes |
| NeMo Guardrails | Policy orchestration in Colang DSL | Under 50ms per check on GPU | Dialog flow control, rail routing |
| Guardrails AI | Python validator framework, 50+ validators | 50 to 200ms per validation | Structured output enforcement |
| Microsoft Presidio | PII recognition and redaction | Varies by entity count | PII detection and masking |
The common production stack. NeMo Guardrails orchestrates the policy layer, calling Llama Prompt Guard 2 (86M) as a fast first-pass gate that catches obvious injection attempts in 20 to 50 milliseconds, and escalating to Llama Guard 3 8B for detailed hazard classification only when the fast gate is uncertain. Presidio handles PII redaction. Guardrails AI enforces structured output on the response.
This cascade structure exists for a specific reason: running an 8B classifier on every request at 459ms p95 latency is not viable for interactive applications. A cascade where 90 percent of requests clear the 20ms gate and only the remainder pay the 459ms classifier cost keeps the average overhead near 90 milliseconds.
The counterintuitive finding on classifier quality. The most capable safety classifier available is open-weight, 8B parameters, and free to run. Llama Guard 3 outperforms GPT-4 used as a moderator on Meta's published benchmark, at roughly one third the false positive rate. Teams that assume a frontier model prompted to moderate will outperform a purpose-built classifier are typically wrong on both accuracy and cost.
The False Positive Tax
The failure mode that kills guardrail deployments is not missed attacks. It is blocked legitimate requests.
Why it happens. A classifier tuned for high recall on adversarial inputs will flag benign inputs that share surface features with attacks. A user asking a security question, a researcher discussing an exploit, a medical professional using clinical terminology, or a customer describing a frustrating experience in strong language can all trip a moderation classifier that was tuned to catch prompt injection and toxic content.
Why it is worse than it looks in testing. Guardrail evaluation typically measures precision and recall on an adversarial test set. It rarely measures the false positive rate on the actual production input distribution, which contains orders of magnitude more benign inputs than adversarial ones. A classifier with 99 percent precision on a balanced test set will block a substantial number of legitimate requests when the real ratio is 10,000 benign requests per adversarial one.
The metric that matters. False positive rate measured on production-representative benign inputs, not on a balanced adversarial benchmark. A guardrail that blocks 3 percent of legitimate traffic is unlikely to survive contact with a product team.
The practical calibration. Run the candidate guardrail in monitoring mode (logging verdicts without blocking) against production traffic for one to two weeks before enabling enforcement. The log tells you the actual false positive rate on your distribution. Teams that skip this step discover the rate from support tickets after enabling blocking.
What the Bypass Research Shows
The honest assessment of guardrail effectiveness requires engaging with the adversarial research rather than the vendor benchmarks.
The empirical findings. Research published in 2025 tested six prominent protection systems, including Microsoft's Azure Prompt Shield and Meta's Prompt Guard, against two evasion approaches: traditional character injection methods and algorithmic adversarial machine learning evasion techniques. Both methods evaded detection while maintaining adversarial utility, achieving up to 100 percent evasion success in some instances.
The research also demonstrated that attackers can improve attack success rates against black-box targets by leveraging word importance ranking computed from offline white-box models, which means an attacker with access to any open-weight guardrail can improve their attack against a closed one.
The judge model vulnerability. OpenAI released its Guardrails safety framework in October 2025, including jailbreak and prompt injection detection pipelines that use an LLM-based judge. Security researchers demonstrated a bypass technique that prompt-injects the judge model and the base model simultaneously, generating harmful outputs without tripping the jailbreak detector and carrying out indirect prompt injection via tool calls without tripping the agentic prompt injection guardrail.
The structural lesson: a guardrail implemented as an LLM judge inherits the vulnerability class it was deployed to defend against. Self-regulation by LLMs cannot fully defend against adversarial manipulation of LLMs.
The adversarial robustness gap in benchmarks. Llama Guard 4 achieves F1 of 0.961 on clean data and 0.796 under adversarial inputs according to General Analysis's 2026 benchmarks. A 17-point F1 drop under adversarial conditions is the honest characterization of what a strong classifier delivers: it substantially reduces attack success, and a determined adversary gets through.
What this means operationally. Guardrails are a probability reduction mechanism, not a guarantee. The architecture that makes an LLM application actually safe does not depend on the guardrail catching every attack. It depends on the damage being bounded when an attack succeeds.
The Defense-in-Depth Architecture
This is the same structural principle that applies to agent security: reduce the frequency of successful manipulation with classifiers, and bound the consequences with structural controls that do not depend on detection.
Layer 1: Classifier-based rails (probabilistic). Input rails, retrieval rails, output rails. These reduce successful attack frequency. Expect them to be bypassed by sufficiently determined adversaries, and tune them for an acceptable false positive rate rather than maximum recall.
Layer 2: Structural controls (deterministic). These hold regardless of whether the classifier caught the attack.
Tool authorization enforced at the mediation layer: an agent that has been successfully jailbroken into attempting an unauthorized action still cannot execute it, because authorization is checked in the application layer rather than in the model's reasoning.
Egress allowlisting: a model manipulated into attempting data exfiltration through a tool call cannot reach an attacker-controlled endpoint, because outbound requests are restricted to approved domains at the network layer.
Output schema enforcement: constrained decoding guarantees the output structure regardless of what the model was manipulated into attempting, which eliminates the class of attacks that work by producing malformed output that breaks downstream parsing.
Tenant scoping at the data layer: a model manipulated into requesting another tenant's data receives nothing, because the query is scoped to the session's tenant at the data access layer rather than depending on the model to request the right scope.
Layer 3: Blast radius limits. Per-session cost ceilings, step count limits, and rate limits per user. These bound the damage from an attack that succeeds at both prior layers. An attacker who successfully jailbreaks a model and evades tool authorization still cannot run an unbounded loop.
The design test. For each guardrail in the stack, ask: if this classifier fails to detect the attack, what prevents the harm? If the answer is "nothing," the guardrail is load-bearing and the architecture has no defense in depth.
The Indirect Injection Gap
One attack class deserves specific attention because input rails miss it structurally.
Direct injection is a user crafting input that overrides the system prompt. The malicious content is in the user message, which input classifiers inspect.
Indirect injection is adversarial content arriving through an external source the model reads: a web page fetched during an agent task, a document retrieved by a RAG pipeline, or a tool result from an external API. The user's message is entirely benign. The malicious instruction is in content the system itself retrieved.
An input classifier inspecting the user message sees nothing wrong, because nothing is wrong with the user message. The attack succeeds without ever passing through the rail that was deployed to catch it.
What catches it. Retrieval rails that filter context chunks before they enter the prompt, and output sanitization that inspects the model's response for signs it followed an injected instruction. Neither is complete: a retrieval rail must detect adversarial content in arbitrary documents, which is the same detection problem the input rail has, with the additional difficulty that the content is not structured as an instruction.
Why this matters more for agents. Tools communicating over MCP are a particularly common vector for indirect prompt injection, because the model has fewer contextual cues that the content arrived from an external source. As covered in GMI Cloud's analysis of what AI agents demand from cloud infrastructure, agents integrate with organizational systems through many connection points, and each integration is a channel through which content reaches the model's context.
The structural mitigation for agents is tool authorization rather than better detection: if the agent cannot execute the action the injected instruction requested, the injection succeeds at manipulating the model and fails at causing harm.
Where Guardrails Sit in the OWASP Threat Map
The OWASP LLM Top 10 provides the threat taxonomy that procurement and security review use. Guardrails address a specific subset.
Covered by guardrails: LLM01 (Prompt Injection), partially, with the indirect injection gap noted above. LLM02 (Insecure Output Handling), through output rails and schema enforcement. LLM06 (Sensitive Information Disclosure), through PII detection and output filtering. LLM07 (System Prompt Leakage), through output rails detecting system prompt disclosure. LLM08 (Excessive Agency), for agentic deployments, through tool call rails.
Not covered by guardrails: supply chain vulnerabilities, training data poisoning, model theft, and the infrastructure security concerns that apply to any production system. These require controls at other layers.
The practical implication for security review: presenting a guardrail deployment as the answer to LLM security addresses roughly half the OWASP threat map. A complete posture requires the structural controls, the infrastructure security, and the supply chain controls alongside the runtime rails.
Monitoring Guardrails in Production
Every guardrail check emits a verdict, and verdicts are events worth treating as first-class telemetry.
Four metrics to track per rail.
Violation rate: the fraction of requests each rail blocks. Track it per rail, not in aggregate, because a rising block rate on one specific rail is a signal and a rising aggregate is noise.
False positive rate: the fraction of blocked requests that were legitimate, determined through sampled human review of blocks. This requires a review process, which is the part most teams skip. Without it, the false positive rate is unknown rather than zero.
Per-check latency at p50 and p95: guardrails sit on the critical path of every request, so their latency is the application's latency. A guardrail whose p95 latency doubles because its classifier endpoint is degraded produces an application-wide latency spike that does not appear in the primary model's metrics.
Coverage: the fraction of model calls that passed through each rail. Gaps in coverage are where incidents happen. A code path that bypasses the guardrail layer, a fallback route that skips it, or an internal service calling the model directly all produce coverage gaps that are invisible unless measured.
Verdict drift as an early signal. A rising block rate on one topic or one tenant flags either an attack campaign or a policy misfit. Both warrant investigation, and the distinction is usually clear from sampling the blocked requests: an attack campaign produces similar adversarial patterns, while a policy misfit produces legitimate requests that the rail was not calibrated for.
At scale this is an analytics problem. A query like "false positive rate by check and application version over the last 30 days" is an aggregation over millions of wide events. Guardrail telemetry belongs in the same observability pipeline as the rest of the application's instrumentation rather than in a separate system.
Infrastructure Requirements for Guardrail Deployment
Guardrail classifiers are inference workloads with a specific and demanding profile.
They sit on the critical path. Unlike observability instrumentation that can run asynchronously, a blocking guardrail must complete before the request proceeds. Its latency adds directly to user-perceived latency, and its availability determines the application's availability.
They are small models with high request volume. Llama Prompt Guard 2 at 86M parameters occupies a fraction of a GPU. Llama Guard 3 at 8B occupies roughly 8 GB at FP8. Neither is VRAM-constrained. Both are latency-constrained, because every request pays their cost.
Cold starts on a guardrail are as damaging as cold starts on the primary model. A guardrail classifier deployed on serverless infrastructure that scales to zero produces a 15 to 30 second cold start on the first request after an idle period, which the user experiences as the application hanging before any processing begins. For guardrails specifically, warm capacity is not an optimization but a requirement.
Deployment on GMI Cloud. GMI Prime Inference provides reserved dedicated capacity with model weights pre-loaded and warm at all times, which eliminates cold start on guardrail classifiers. The per-model runtime tuning applies to guardrail models as it does to generation models: a classifier tuned for minimum latency at the batch sizes guardrail traffic produces runs meaningfully faster than one running generic serving parameters.
For the cascade architecture, the practical configuration colocates the fast first-pass classifier (86M parameters) with other small models on shared GPU capacity, and reserves capacity for the 8B hazard classifier separately, since it is invoked less frequently but has a substantially larger latency cost when it runs.
For teams benchmarking classifier options before committing, GMI Cloud's on-demand infrastructure provides hourly billing with no minimum commitment, making it practical to measure false positive rate and latency for candidate guardrail models on production-representative traffic.
A Deployment Sequence That Works
Phase 1: Monitoring mode. Deploy the guardrail with blocking disabled, logging every verdict against production traffic. Run for one to two weeks. This produces the actual false positive rate on your input distribution, which no benchmark provides.
Phase 2: Calibration. Review the sampled blocks. Adjust thresholds, disable rails whose false positive rate is unacceptable, and add rails for attack patterns the monitoring revealed. The output is a configuration calibrated to your traffic rather than to a benchmark.
Phase 3: Enforcement on high-confidence rails only. Enable blocking for the rails with the lowest false positive rates first, typically PII detection and obvious injection patterns. Keep the higher-variance rails in monitoring mode.
Phase 4: Structural controls. Implement tool authorization, egress allowlisting, output schema enforcement, and blast radius limits. This is the layer that bounds damage when the rails are bypassed, and it should be in place before the deployment is considered complete.
Phase 5: Red team. Test the deployed configuration with adversarial inputs, including character injection, encoded instructions, multi-turn escalation, and indirect injection through retrieved content. Tools such as PyRIT, Garak, and Promptfoo automate parts of this. The objective is not zero successful attacks, which is not achievable, but confirmation that successful attacks cannot cause critical harm because Phase 4 controls hold.
Conclusion
Guardrails are necessary and insufficient. They reduce the frequency of successful attacks meaningfully, and the published adversarial research is clear that they can be evaded: up to 100 percent evasion success against six prominent systems using character injection and adversarial ML techniques, and a demonstrated bypass of OpenAI's own Guardrails framework by prompt-injecting the judge and base models simultaneously.
The architecture that makes an LLM application safe does not depend on the guardrail catching every attack. Classifier-based rails reduce attack frequency. Structural controls that do not depend on detection, meaning tool authorization, egress allowlisting, output schema enforcement, and tenant scoping at the data layer, bound the damage when the rails are bypassed. Blast radius limits bound it further.
The operational reality of running guardrails: they sit on the critical path of every request, which makes their latency the application's latency and their availability the application's availability. Deploy them in monitoring mode first to measure the false positive rate on your actual traffic distribution, because a guardrail that blocks legitimate users is the failure mode that ends deployments, not the attack it missed.
Deploy guardrail models on GMI Cloud
FAQs
Can LLM guardrails be bypassed, and how reliably? Yes. Research published in 2025 tested six prominent protection systems including Microsoft's Azure Prompt Shield and Meta's Prompt Guard against character injection and adversarial machine learning evasion techniques, achieving up to 100 percent evasion success in some instances while maintaining adversarial utility. Separately, OpenAI's Guardrails framework released in October 2025 was bypassed by a technique that prompt-injects the LLM judge and the base model simultaneously, evading both the jailbreak detector and the agentic prompt injection detector. Even strong classifiers show meaningful degradation under adversarial conditions: Llama Guard 4 achieves F1 of 0.961 on clean data and 0.796 under adversarial inputs. Guardrails are a probability reduction mechanism, and the architecture must bound the damage from attacks that succeed.
What is the typical latency cost of a production guardrail stack? Approximately 90 milliseconds for a well-designed cascade. The structure that achieves this: a fast local scanner such as LLM Guard at under 10 milliseconds per check, a small injection classifier such as Llama Prompt Guard 2 at 86M parameters running in 20 to 50 milliseconds on H100 with FP8, and escalation to a detailed hazard classifier such as Llama Guard 3 8B only when the fast gates are uncertain. Running the 8B classifier on every request is not viable for interactive applications, because Llama Guard 4 posts approximately 459 milliseconds p95 latency on typical GPU hardware. The cascade keeps average overhead near 90 milliseconds by ensuring most requests clear the fast gates.
Why do input classifiers fail to catch indirect prompt injection? Because the user message is benign. In indirect injection, the adversarial instruction arrives through content the system itself retrieved: a document surfaced by a RAG pipeline, a web page fetched during an agent task, or a tool result from an external API. An input classifier inspecting the user message finds nothing wrong, because nothing is wrong with the user message. Catching this attack class requires retrieval rails that filter context chunks before prompt assembly and output sanitization that detects signs the model followed an injected instruction. Neither is complete, which is why tool authorization at the infrastructure layer is the more reliable mitigation for agentic systems: if the agent cannot execute the requested action, the injection succeeds at manipulation and fails at causing harm.
What is the false positive tax and how should it be measured? The false positive tax is legitimate requests blocked by a guardrail tuned aggressively for attack detection. It is measured incorrectly by most teams, because guardrail evaluation typically reports precision and recall on a balanced adversarial test set while production traffic contains orders of magnitude more benign requests than adversarial ones. A classifier with 99 percent precision on a balanced benchmark blocks a substantial number of legitimate requests when the real ratio is 10,000 benign per adversarial. The correct measurement is false positive rate on production-representative benign traffic, obtained by running the guardrail in monitoring mode with blocking disabled for one to two weeks and sampling the would-be blocks for human review.
Which structural controls hold when guardrails are bypassed? Four controls that do not depend on detection. Tool authorization enforced at the mediation layer means a successfully jailbroken model still cannot execute an unauthorized action, because authorization is checked in the application layer rather than in the model's reasoning. Egress allowlisting means a model manipulated into attempting exfiltration cannot reach an attacker-controlled endpoint, because outbound requests are restricted at the network layer. Output schema enforcement through constrained decoding guarantees the output structure regardless of what the model was manipulated into producing. Tenant scoping enforced at the data access layer means a model manipulated into requesting another tenant's data receives nothing. Per-session cost ceilings and step limits bound the damage further. The design test for any guardrail: if this classifier fails to detect the attack, what prevents the harm?
Build AI Without Limits
GMI Cloud helps you architect, deploy, optimize, and scale your AI strategies
FAQ
Yes. Research published in 2025 tested six prominent protection systems including Microsoft's Azure Prompt Shield and Meta's Prompt Guard against character injection and adversarial machine learning evasion techniques, achieving up to 100 percent evasion success in some instances while maintaining adversarial utility. Separately, OpenAI's Guardrails framework released in October 2025 was bypassed by a technique that prompt-injects the LLM judge and the base model simultaneously, evading both the jailbreak detector and the agentic prompt injection detector. Even strong classifiers show meaningful degradation under adversarial conditions: Llama Guard 4 achieves F1 of 0.961 on clean data and 0.796 under adversarial inputs. Guardrails are a probability reduction mechanism, and the architecture must bound the damage from attacks that succeed.