Speculative Decoding for LLM Inference: How Draft Models Cut Latency Without Quality Loss
September 16, 2026
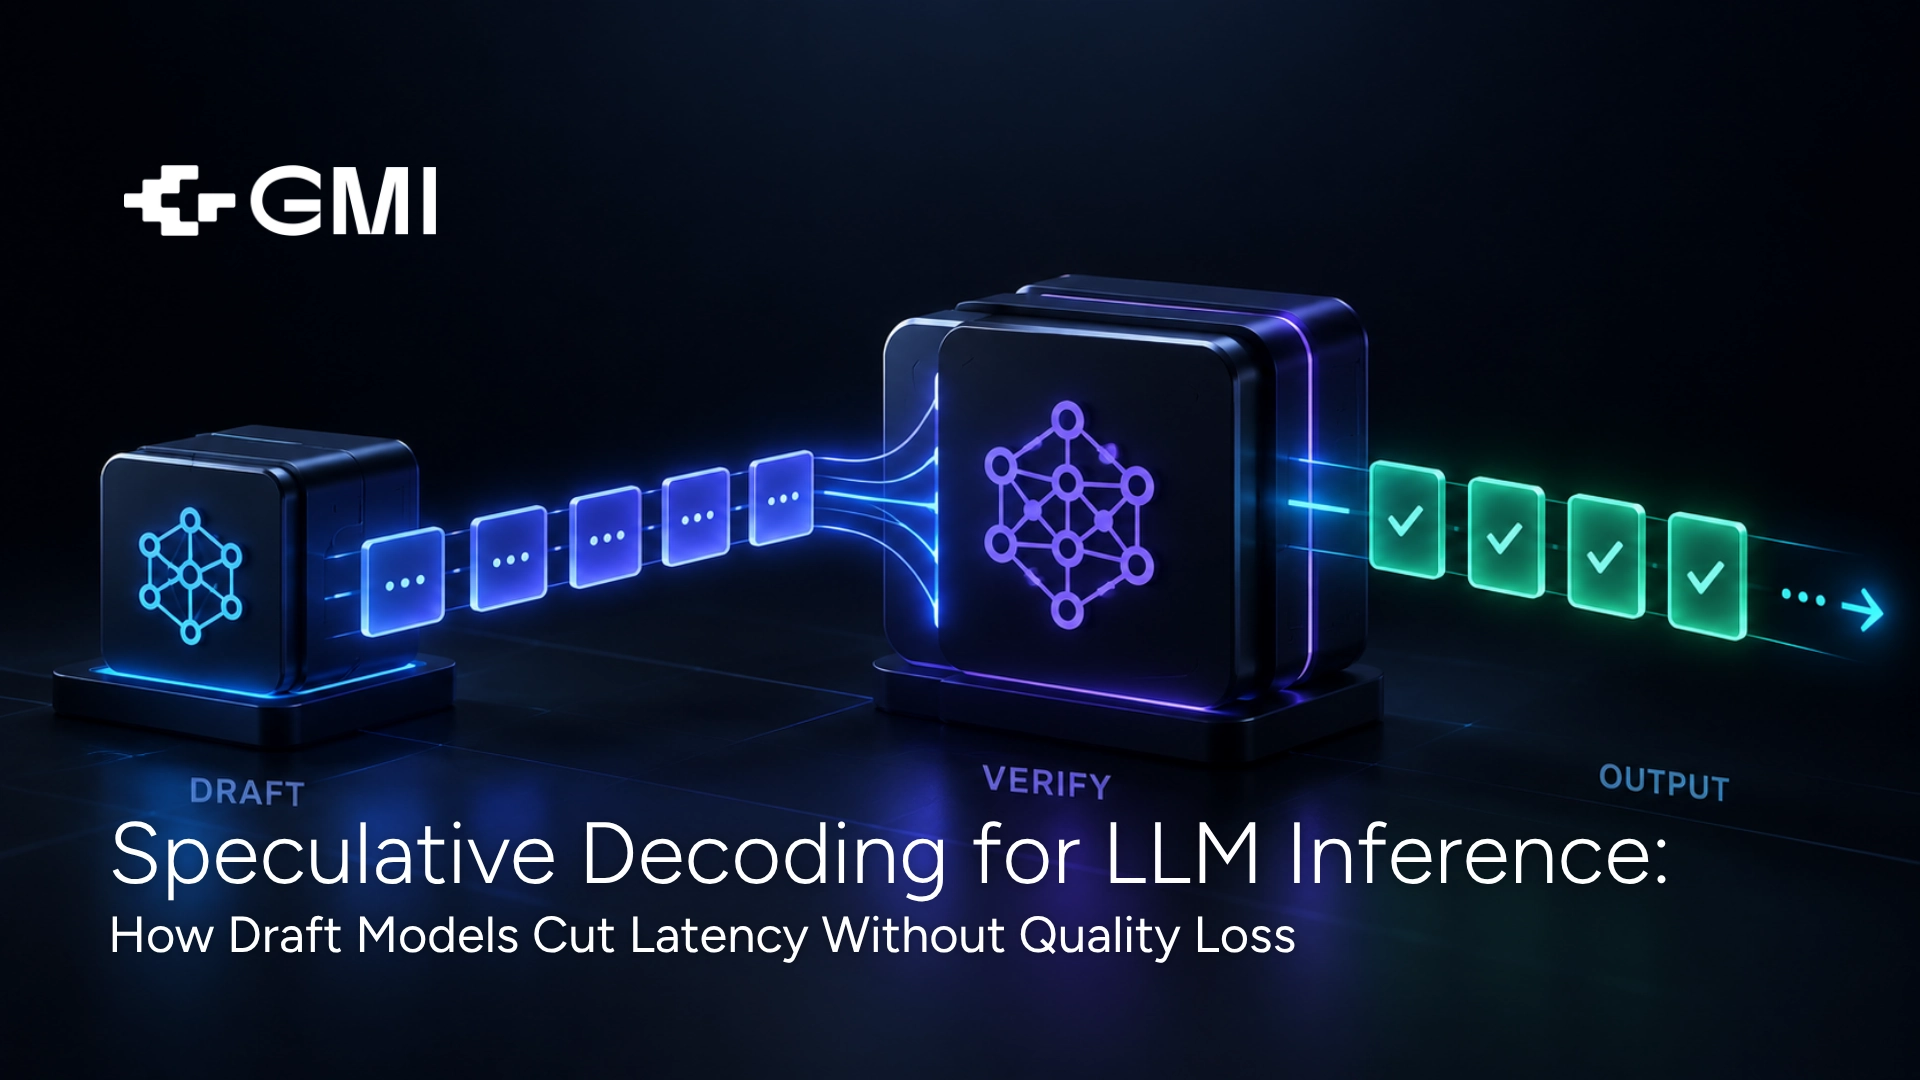
Autoregressive generation wastes most of a modern GPU's compute capacity. Producing one token requires a full forward pass through the model, which means streaming every weight from VRAM into the compute units, performing the attention computation, and emitting a single token. For a 70B model on an H100, that is roughly 30 to 50 milliseconds of work per token, and the overwhelming majority of that time is memory movement rather than arithmetic. The tensor cores sit largely idle while the memory bus saturates. Speculative decoding exploits this imbalance: a small draft model proposes several tokens ahead, the target model verifies all of them in a single forward pass, and the accepted tokens are emitted together. The memory movement cost stays roughly the same as one forward pass while the output can be several tokens, and the verification step guarantees the output is identical to what the target model would have produced alone.
- Speculative decoding is a memory-bandwidth optimization, not a compute optimization. It spends spare GPU compute to reduce memory movement. This is why the speedup is largest at low batch sizes, where inference is memory-bound, and disappears or reverses at high batch sizes, where inference becomes compute-bound.
- Output quality is mathematically unchanged. The verification step accepts draft tokens only when they match what the target model would have sampled, which means the output distribution is identical to non-speculative generation. This is not an approximation with a quality tradeoff.
- GMI Prime Inference ships with vLLM, SGLang, and TensorRT-LLM pre-configured, all of which include production-ready speculative decoding implementations. The per-model runtime tuning includes the speculative configuration appropriate to the model and its expected batch size profile.
- EAGLE-3 is the practical default in 2026. On Llama-3.3-70B chat at batch size 1 on H100 SXM with FP8 weights and KV cache, it produces 3.0 to 3.4 times decode speedup over a non-speculative baseline, with acceptance rates of 0.80 to 0.88 on coding and instruction-following tasks. It is one flag in vLLM, not a rewrite.
- Acceptance rate is the metric that tells you whether it is working. Read acceptance length before throughput: if the draft model's proposals are rejected frequently, the verification overhead exceeds the savings and the deployment is slower than the baseline.
- The most common configuration error is a tokenizer mismatch. A draft checkpoint whose tokenizer does not exactly match the target model's tokenizer produces low acceptance rates and a net slowdown, with no error message indicating the cause.
Why Autoregressive Generation Leaves GPU Capacity Unused
Understanding the mechanism requires understanding what actually constrains decode throughput.
The sequential constraint. Standard generation runs a forward pass with the current context, samples the next token from the output distribution, appends it to the context, and repeats. Each step depends on the previous one, which means the steps cannot be parallelized.
The memory bandwidth bottleneck. Each forward pass loads the full model weights from VRAM into compute units. For a 70B model at FP8, that is 70 GB of weight data moved per token generated. On an H100 at 3.35 TB/s of memory bandwidth, moving 70 GB takes approximately 21 milliseconds. The arithmetic performed on those weights for a single token is a tiny fraction of what the tensor cores can execute in that time.
The consequence. At batch size 1, a modern GPU running LLM decode is memory-bound by a wide margin. The FLOPs available substantially exceed the FLOPs required. Generating more tokens per unit of memory movement is nearly free in compute terms, which is exactly the opportunity speculative decoding exploits.
Why batching partially solves this and why that matters here. Continuous batching processes multiple requests simultaneously, which amortizes the weight loading across many tokens. At batch size 32, one weight load produces 32 tokens rather than one, which is a 32x improvement in memory efficiency. This is also why speculative decoding's benefit shrinks as batch size grows: batching already captured the memory efficiency that speculation was recovering.
How Speculative Decoding Works
The draft and verify loop.
A draft model, which is substantially smaller and faster than the target model, generates K candidate tokens autoregressively. K is typically 3 to 8.
The target model then processes all K candidate tokens in a single forward pass. Because the tokens are already proposed, the target model can evaluate them in parallel rather than sequentially, which is the same operation it performs during prefill.
The verification compares what the target model would have sampled at each position against what the draft proposed. Tokens are accepted from the beginning of the sequence until the first mismatch. All tokens before the mismatch are emitted; the mismatched token is replaced with the target model's own sample; everything after is discarded.
The loop repeats from the new position.
Why the output is identical to non-speculative generation.
This is the property that distinguishes speculative decoding from quantization, pruning, and other acceleration techniques that trade quality for speed. The acceptance criterion is constructed so that the resulting token distribution exactly matches the target model's distribution. A token is accepted only when accepting it produces the same statistical outcome as sampling from the target model directly.
The practical implication: speculative decoding requires no quality evaluation before deployment. The output is provably the same. The only question is whether it is faster, which depends on the acceptance rate and the batch size.
Where the time is saved.
If the draft proposes 5 tokens and all 5 are accepted, the system emitted 5 tokens for the memory cost of one target model forward pass plus 5 cheap draft forward passes. If 3 of 5 are accepted, it emitted 4 tokens (3 accepted plus the target's correction) for the same cost. If 0 are accepted, it emitted 1 token and wasted the draft computation, which is slower than the baseline for that step.
The average number of tokens emitted per verification step is the acceptance length, commonly denoted tau. This single number determines whether the deployment is faster or slower than the baseline.
The Batch Size Tradeoff
This is the decision factor that determines whether speculative decoding helps or hurts a given deployment, and it is the part most commonly misunderstood.
The framing that clarifies it. Speculative decoding spends extra compute to reduce memory movement. At low request rates, inference is memory-bound, so reducing memory movement directly reduces latency. At high throughput or large batch sizes, inference becomes compute-bound, and spending extra compute makes things worse.
What this looks like in numbers.
At batch size 1, EAGLE-3 on Llama-3.3-70B produces 3.0 to 3.4 times decode speedup on H100 SXM with FP8 weights and KV cache.
At batch size 4 on Llama-3.1-8B, benchmarks show approximately 2.3 times speedup.
Larger models see larger speedups at equivalent batch sizes, typically 4 to 6 times for 70B and above, because the draft head's overhead becomes negligible relative to the target model's cost while the memory bandwidth savings grow with model size.
Above batch size 32, the recommendation from serving framework maintainers is generally to disable speculative decoding. At high concurrency, the target model is already compute-saturated by the batch, the draft head's acceptance benefits shrink, and verification overhead dominates.
Research on the FastEagle variant found EAGLE-3 peaking at batch size 56 and FastEagle peaking at 32, with the difference attributed to memory pressure from the additional KV cache states that the draft mechanism maintains.
The practical rule. Speculative decoding is a low-load latency optimization. Deploy it for workloads where requests arrive at rates that leave the GPU underutilized, and disable it for workloads that saturate the GPU with concurrent requests.
The workloads where this fits. Interactive applications with modest concurrency where per-request latency is the quality metric: coding assistants, voice AI, real-time chat with a small user base, and agentic pipelines where steps execute sequentially rather than in parallel batches. These are precisely the workloads where time to first token and inter-token latency matter most and where the GPU is not otherwise saturated.
The workloads where it does not fit. High-throughput batch processing, document pipelines, and any deployment running at sustained high concurrency. These are compute-bound, and speculative decoding adds work without recovering time.
The Variants and When to Use Each
Five approaches are available in production serving frameworks as of 2026, with meaningfully different tradeoffs.
n-gram lookup (no neural draft model).
Instead of a draft model, the system matches patterns against the prompt and prior output history, proposing continuations found in the existing context. Zero additional VRAM, zero training, and near-zero draft compute cost.
Best for input-grounded and repetitive tasks: RAG where the answer quotes retrieved passages, code editing where the output largely reproduces the input with modifications, structured data transformation, and summarization that reuses source phrasing. Acceptance rates on these tasks can be high because the output genuinely repeats content present in the context.
Poor for open-ended generation where the output does not repeat the input.
Medusa (multiple prediction heads).
Adds several prediction heads to the target model, each predicting a token at a different future position. Self-contained: no separate draft model to load or maintain. Trainable on a single GPU with self-distillation when no separate training data is available.
Best for teams deploying custom models where no pre-trained draft head exists and training one is feasible. The integration complexity is higher than EAGLE but the architecture is simpler.
EAGLE-2 (draft head on last hidden state).
Trains a lightweight transformer head that drafts in feature space rather than token space, taking the target model's last hidden state as input. Substantially higher acceptance rates than naive draft models because the draft operates on the target's own internal representations.
On Llama-3.3-70B chat at batch 1 on H100 SXM FP8: 2.4 to 2.7 times decode speedup.
EAGLE-3 (feature fusion across layers).
Generalizes EAGLE-2 by training the draft head against a mixture of intermediate hidden states from all transformer layers rather than only the last layer. The additional context improves acceptance rates by 8 to 14 percent on chat tasks and 4 to 9 percent on code, with the same KV cache footprint.
On Llama-3.3-70B chat at batch 1 on H100 SXM FP8: 3.0 to 3.4 times decode speedup. Acceptance rates of 0.80 to 0.88 on coding and instruction-following tasks.
This is the practical default for 2026 deployments. Pre-trained EAGLE-3 heads exist for popular target models on Hugging Face, and enabling it in vLLM is a flag rather than an integration project.
P-EAGLE (parallel drafting).
EAGLE-3's remaining limitation is that drafting is itself autoregressive: generating K draft tokens requires K sequential forward passes through the draft head, so draft overhead grows linearly with K. P-EAGLE removes this ceiling by generating all K draft tokens in a single forward pass through a lightweight multi-layer draft network.
This is the current state of the art for EAGLE-based speculative decoding. For teams deploying EAGLE in 2026, P-EAGLE is the variant to evaluate.
MTP (multi-token prediction heads).
Extra prediction heads pretrained jointly with the target model rather than trained afterward. Architecturally closer to Medusa than EAGLE, but the joint pretraining produces meaningfully higher acceptance rates because the heads learned alongside the model rather than approximating it after the fact.
Popularized by DeepSeek-V3 and adopted by several frontier labs. Available only for models that shipped with MTP heads; cannot be added to a model that was not pretrained with them.
Acceptance Rate: The Metric to Read First
Acceptance rate, or equivalently acceptance length tau, is the average number of draft tokens accepted per verification step. It determines whether the deployment is faster or slower than baseline, and it should be checked before throughput measurements.
Why it is the leading indicator. Throughput measurements conflate acceptance rate with batch size effects, hardware utilization, and serving configuration. Acceptance rate isolates the question of whether the draft model is actually predicting the target model well on your workload.
Expected values. EAGLE-3 achieves 0.80 to 0.88 acceptance on coding and instruction-following tasks. An acceptance rate below 0.5 indicates a problem: the draft model is mismatched to the workload, the tokenizer does not match, or the draft checkpoint is for a different target model version.
What lowers acceptance rate.
Tokenizer mismatch between the draft checkpoint and the target model. This is the most common configuration error, and it produces low acceptance with no error message. Verify that the draft checkpoint's tokenizer matches the target's exactly before debugging anything else.
Workload mismatch. A draft head trained primarily on chat data will show lower acceptance on code generation, and an n-gram drafter will show very low acceptance on open-ended creative generation.
Aggressive quantization on the target model. INT4 weights drop acceptance by roughly 3 to 5 percentage points relative to FP8, because the quantized target model's sampling diverges slightly from what the draft head was trained to predict.
High sampling temperature. Higher temperature produces more diverse target sampling, which the draft head predicts less reliably.
The K tuning relationship. The optimal number of draft tokens K depends on the acceptance rate. With high acceptance, a larger K captures more tokens per verification step. With low acceptance, a large K wastes draft computation on tokens that will be discarded. Typical production values are 3 to 5 for EAGLE-3, with 5 being a reasonable starting point.
Configuration and Framework Interactions
vLLM setup.
For EAGLE-3 on Llama 3.3 70B, the relevant flags specify the draft model checkpoint, the number of speculative tokens, the draft model's tensor parallel size, and GPU memory utilization:
--speculative-model yuhuili/EAGLE3-LLaMA3.3-Instruct-70B
--num-speculative-tokens 5
--speculative-draft-tensor-parallel-size 1
--gpu-memory-utilization 0.94
Newer vLLM versions consolidate these into a --speculative-config parameter. P-EAGLE adds "parallel_drafting": true to the configuration.
The elevated --gpu-memory-utilization value accounts for the draft head's VRAM footprint alongside the target model and KV cache.
SGLang setup.
SGLang exposes speculative_num_steps (the draft depth, typically 5) and speculative_eagle_topk (the tree width for tree-based drafting, typically 8). SGLang's RadixAttention KV cache is fully compatible with EAGLE-3 draft verification, so prefix caching and speculative decoding compose without conflict.
Interaction with quantization.
The standard 2026 production pattern is FP8 target, FP8 draft, FP8 KV cache. INT4 target weights reduce acceptance by 3 to 5 points, but the compute savings on the draft side often outweigh the acceptance loss because draft FLOPs become nearly free, which permits a slightly larger K.
Interaction with chunked prefill.
The two techniques are orthogonal in their mechanism: chunked prefill splits prefill compute into smaller batches to overlap with decode in continuous batching, while speculative decoding operates entirely in the decode phase.
The interaction worth knowing: when a long prompt is being chunk-prefilled, decode tokens for other in-flight requests run speculative verification against a target model that is simultaneously performing prefill work. Verification calls compete with prefill chunks for tensor core time. vLLM's scheduler prioritizes verification batches over prefill chunks when decode tokens are nearly complete; SGLang inverts this priority. For latency-sensitive deployments, this scheduler difference is worth measuring rather than assuming.
VRAM cost.
The draft head occupies VRAM alongside the target model and KV cache. EAGLE-3 heads are small (a single-layer or few-layer transformer), so the footprint is modest, but it reduces available KV cache space. For deployments where KV cache is the binding constraint on concurrency, the draft head's footprint shifts the concurrency ceiling slightly downward.
The Deployment Decision
Enable speculative decoding when:
Average batch size stays below roughly 16 to 32 during normal operation. This is the primary criterion.
Per-request latency is the quality metric rather than aggregate throughput. Interactive applications, coding assistants, voice AI, and sequential agent pipelines fit this profile.
The model is 30B parameters or larger. Larger models see proportionally larger speedups because the draft overhead is a smaller fraction of the target model's cost.
A pre-trained EAGLE-3 head exists for the target model, which removes the training requirement entirely.
Skip speculative decoding when:
The deployment runs at sustained high concurrency. Above batch size 32, verification overhead typically exceeds the memory bandwidth savings.
The workload is batch processing where throughput matters and latency does not.
VRAM is already the binding constraint on concurrency, and the draft head's footprint would reduce the concurrent session count meaningfully.
The measurement that decides it. Run the workload with speculative decoding enabled and disabled at your actual production batch size distribution, and compare p50 and p95 latency plus total throughput. The paper speedups are measured at batch size 1; your number is the one that matters.
Deployment on GMI Cloud
Speculative decoding is a serving stack configuration, which makes the serving framework and its tuning a deployment consideration.
Pre-configured frameworks with speculative support. GMI Prime Inference nodes ship with vLLM, SGLang, and TensorRT-LLM pre-installed and tuned per GPU class. All three include production-ready speculative decoding implementations, which means enabling EAGLE-3 is a configuration change rather than a framework installation and version compatibility exercise.
Per-model runtime tuning includes speculative configuration. The tuning applied per model and per GPU class covers the speculative parameters: whether speculation is enabled for the model's expected batch size profile, the draft checkpoint selection, and the K value calibrated to the acceptance rate observed on representative traffic. A model deployed for a low-concurrency interactive workload receives a different speculative configuration than the same model deployed for batch processing.
Warm endpoints matter for the draft model too. The draft head is loaded alongside the target model. On serverless infrastructure that scales to zero, both pay cold start. Prime Inference's reserved capacity keeps both resident in VRAM continuously.
Measuring the tradeoff on your workload. Because the speedup depends entirely on your batch size distribution, the deciding measurement must run on your traffic rather than a benchmark. GMI Cloud's on-demand infrastructure provides hourly billing with no minimum commitment, which makes it practical to measure acceptance rate and end-to-end latency with speculation enabled and disabled before committing to a configuration.
For teams working through the broader price-performance question, GMI Cloud's analysis of the inference price-performance sweet spot covers how batch size, model size, and latency tolerance interact to determine the optimal configuration, which is the same set of variables that determines whether speculative decoding helps.
Conclusion
Speculative decoding is the rare inference optimization with no quality tradeoff: the verification step guarantees the output distribution matches non-speculative generation exactly. What it trades is compute for memory bandwidth, which is why its value depends entirely on whether your deployment is memory-bound or compute-bound.
At low batch sizes, inference is memory-bound and the speedup is substantial: 3.0 to 3.4 times decode speedup for EAGLE-3 on Llama-3.3-70B at batch size 1, and 4 to 6 times for larger models. Above batch size 32, continuous batching has already captured the memory efficiency that speculation recovers, and the verification overhead makes it counterproductive.
EAGLE-3 is the practical default: pre-trained heads exist for popular targets, acceptance rates reach 0.80 to 0.88 on coding and instruction-following tasks, and enabling it is one flag rather than an integration project. Check acceptance rate before throughput, verify the draft tokenizer matches the target exactly, and measure at your actual batch size distribution rather than trusting the batch-size-1 benchmarks.
Start with GMI Cloud for optimized inference
FAQs
Does speculative decoding reduce output quality? No, and this is mathematically guaranteed rather than empirically observed. The verification step accepts a draft token only when accepting it produces the same statistical outcome as sampling directly from the target model. The resulting output distribution is identical to non-speculative generation. This distinguishes speculative decoding from quantization, pruning, and distillation, all of which trade some quality for speed. The practical implication is that speculative decoding requires no quality evaluation before deployment; the only question is whether it is faster on your workload.
Why does speculative decoding stop helping at high batch sizes? Because it spends compute to reduce memory movement, and at high batch sizes the deployment is no longer memory-bound. At batch size 1, generating one token requires streaming the full model weights from VRAM, and the GPU's tensor cores are largely idle during that memory transfer. Speculation uses that spare compute to verify multiple tokens per weight load. Continuous batching achieves the same memory efficiency differently: at batch size 32, one weight load produces 32 tokens. Once batching has captured that efficiency, the target model becomes compute-saturated, and the draft computation plus verification overhead makes the deployment slower rather than faster. Framework maintainers generally recommend disabling speculative decoding above batch size 32.
Which speculative decoding variant should a production deployment use? EAGLE-3 is the practical default for 2026. Pre-trained EAGLE-3 heads exist on Hugging Face for popular target models, enabling it in vLLM is a single flag rather than an integration project, and it achieves acceptance rates of 0.80 to 0.88 on coding and instruction-following tasks with 3.0 to 3.4 times decode speedup at batch size 1 on Llama-3.3-70B. Two alternatives fit specific cases: n-gram lookup requires zero additional VRAM and performs well on input-grounded tasks like RAG and code editing where the output repeats content from the context; P-EAGLE removes EAGLE-3's autoregressive drafting bottleneck by generating all draft tokens in a single forward pass and is the current state of the art for EAGLE-based methods.
What is acceptance rate and why should it be checked before throughput? Acceptance rate, or acceptance length tau, is the average number of draft tokens accepted per verification step, and it determines whether the deployment is faster or slower than the baseline. It should be read first because throughput measurements conflate acceptance rate with batch size effects, hardware utilization, and serving configuration, while acceptance rate isolates whether the draft model is actually predicting the target well on your workload. Expected values for EAGLE-3 are 0.80 to 0.88 on coding and instruction-following tasks. An acceptance rate below 0.5 signals a problem, most commonly a tokenizer mismatch between the draft checkpoint and the target model, which produces low acceptance with no error message indicating the cause.
How does speculative decoding interact with quantization and prefix caching? With quantization: the standard 2026 production pattern is FP8 target, FP8 draft, and FP8 KV cache. Moving the target model to INT4 reduces acceptance rate by roughly 3 to 5 percentage points, because the quantized model's sampling diverges slightly from what the draft head was trained to predict. The compute savings on the draft side often outweigh this loss, permitting a slightly larger draft depth. With prefix caching: SGLang's RadixAttention is fully compatible with EAGLE-3 draft verification, so prefix sharing and speculation compose without conflict. The interaction worth measuring is with chunked prefill, where verification calls compete with prefill chunks for tensor core time, and vLLM and SGLang schedulers resolve that contention with opposite priorities.
Build AI Without Limits
GMI Cloud helps you architect, deploy, optimize, and scale your AI strategies
FAQ
No, and this is mathematically guaranteed rather than empirically observed. The verification step accepts a draft token only when accepting it produces the same statistical outcome as sampling directly from the target model. The resulting output distribution is identical to non-speculative generation. This distinguishes speculative decoding from quantization, pruning, and distillation, all of which trade some quality for speed. The practical implication is that speculative decoding requires no quality evaluation before deployment; the only question is whether it is faster on your workload.